Why every fact our AI extracts must quote its source
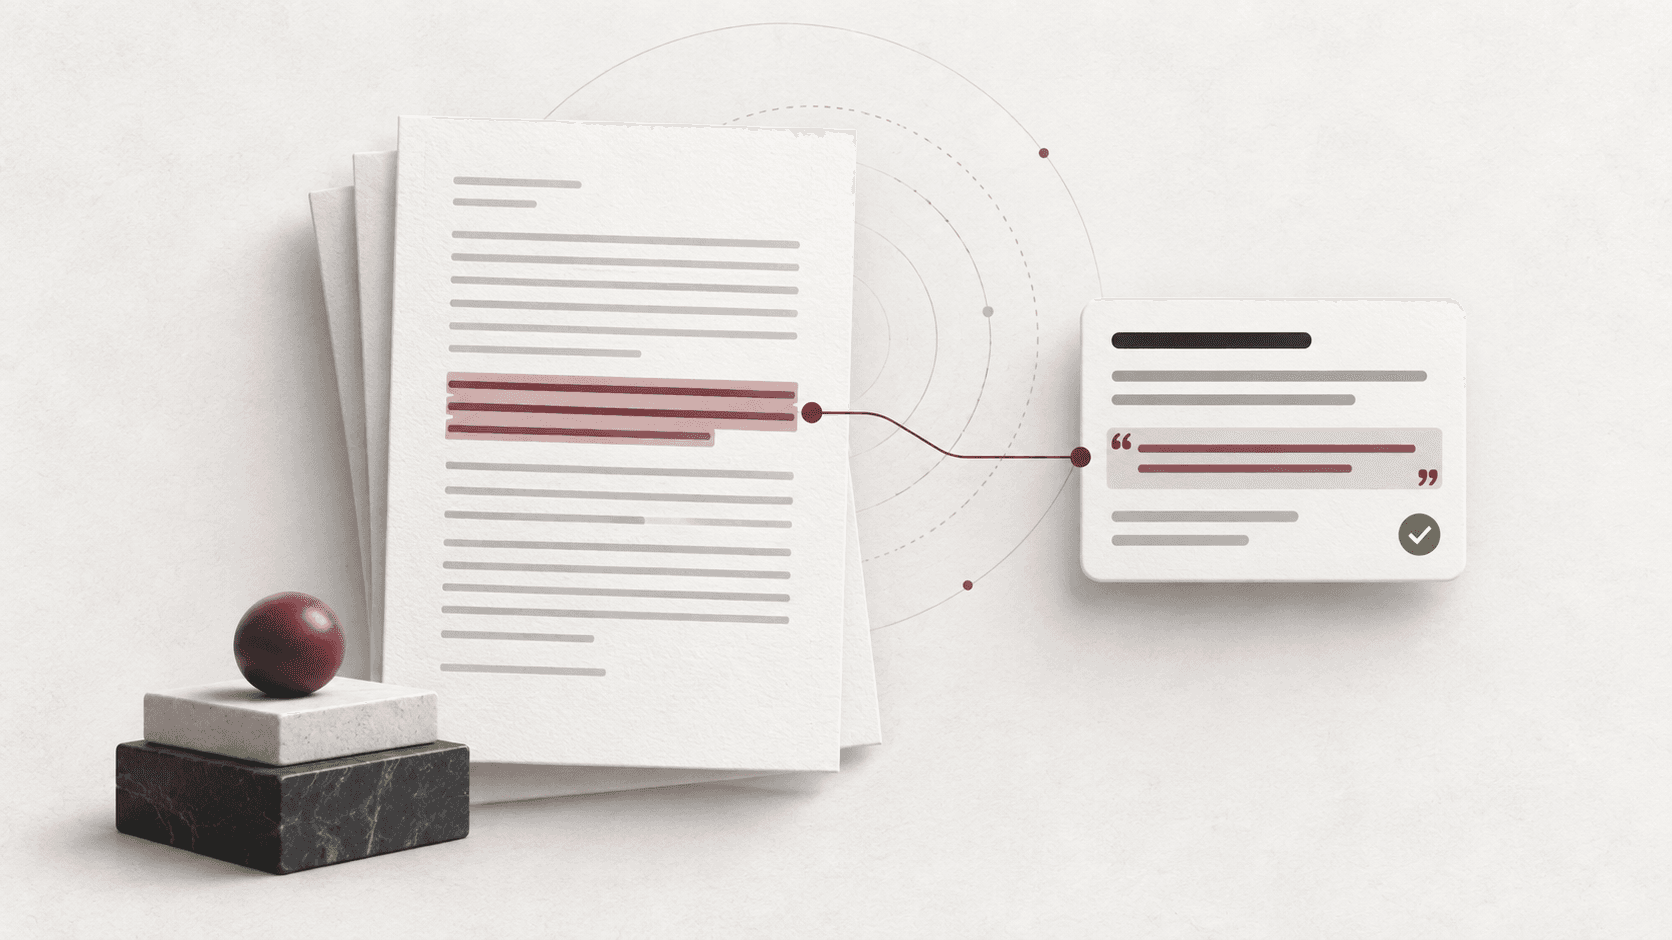
ResearchRadar keeps an extracted fact only when it can point to the exact sentence in your document that supports it. The quote is checked mechanically: if it is not a perfect substring of the source, the fact is rejected.
ResearchRadar has one job: you give it a paper, thesis, or proposal, and it watches the field for developments that matter to that work. That only works when the system has an accurate account of what your document says. Language models are fluent but unreliable readers: they can let meaning drift while paraphrasing, or state something the document never said.
An alert built on an invented fact wastes exactly the attention it is meant to protect. That is why a rule we made early shapes the rest of the product.
The rule: no quote, no fact. Nothing extracted from your document enters the system as knowledge unless it carries a verbatim quote from that document. The quote is checked mechanically, not accepted on another model's opinion.
What does a grounded fact look like?
When the extraction loop reads a document, every candidate becomes a typed record, not loose prose. It identifies the kind of fact — a research topic, method, claimed result, limitation, or funding source — and carries the verbatim quote and position it rests on. It also states its status honestly: stated by the document, implied by it, or not reported.
That last one matters more than it looks. "Not reported" is treated as a finding, never as an error. If a paper doesn't state how mature its method is, the honest answer is the paper doesn't say — not a guess dressed up as knowledge.
How is the quote actually checked?
Every candidate is checked before it is admitted, in three steps, from cheapest to most expensive:
- The exact-substring check. Is the quote a character-for-character substring of the source document? This deterministic string comparison cannot be persuaded by a fluent answer. A model that invents or “cleans up” a quote fails here.
- Schema validation. Does the fact parse into its typed shape — the right fields, the right kinds of values? Malformed facts are rejected before any further spending.
- The entailment check. A separate, cheaper model reads only the quoted spans, never the whole document, and judges whether they support the claim. It cannot “helpfully” find alternative evidence the extractor never cited.
Only facts that survive all three steps become part of what the radar knows about your document. Everything else is discarded or kept only as a flagged, unverified candidate for human inspection.
Why not just use confidence scores?
Because a confidence score is a self-assessment, and you cannot audit a self-assessment. Models can be confidently wrong; a number between 0 and 1 reports how the model feels, not whether the fact is true.
A quote changes the relationship. You, a reviewer, or a skeptical juror can open the document, find the sentence, and compare it with the claim. The evidence is part of the interface. When the public evaluation page is live, the grounding rate — the share of admitted facts passing the exact-substring check — will be measured mechanically on every run. Until then, we describe the mechanism, not unmeasured results.
What this buys the radar
Everything downstream inherits this evidence trail. When ResearchRadar alerts you that a new paper matches your work, “why am I seeing this?” should lead to an answer you can read, not a similarity score you have to trust. That is the difference between a radar and a firehose: signal you can audit.
Questions we get
What is span-grounded extraction?
It means every fact an AI pulls from a document is stored together with the exact text span — the verbatim quote and its position — that supports it. If no span in the document states the fact, it is not recorded as knowledge; it is rejected or marked as not reported.
Why can't the AI just say how confident it is?
A confidence score is a self-assessment you cannot audit — models are routinely confident and wrong. A quote is different: you can read the sentence yourself and check it against the claim. We prefer one piece of checkable evidence over any amount of self-reported certainty.
Does this make extraction slower or more expensive?
The exact-substring check is free — it is string comparison, not an AI call. The added cost sits in the verification pass, where a second, cheaper model checks that the quoted spans actually support each claim. We consider that the price of publishing facts we can stand behind.